The problem
An A/B test on a shop page is usually read off a dashboard that names a winner as soon as one arm is ahead. With a purchase rate near 5 %, thousands of showings an arm still cannot tell a 10 % difference from luck, so many winners are noise.
The next question is personalisation: instead of one winner for everybody, show each shopper the version that suits them. That only pays when the shop can see who prefers what, and most of the time it cannot tell well enough to beat the plain winner.
How it works
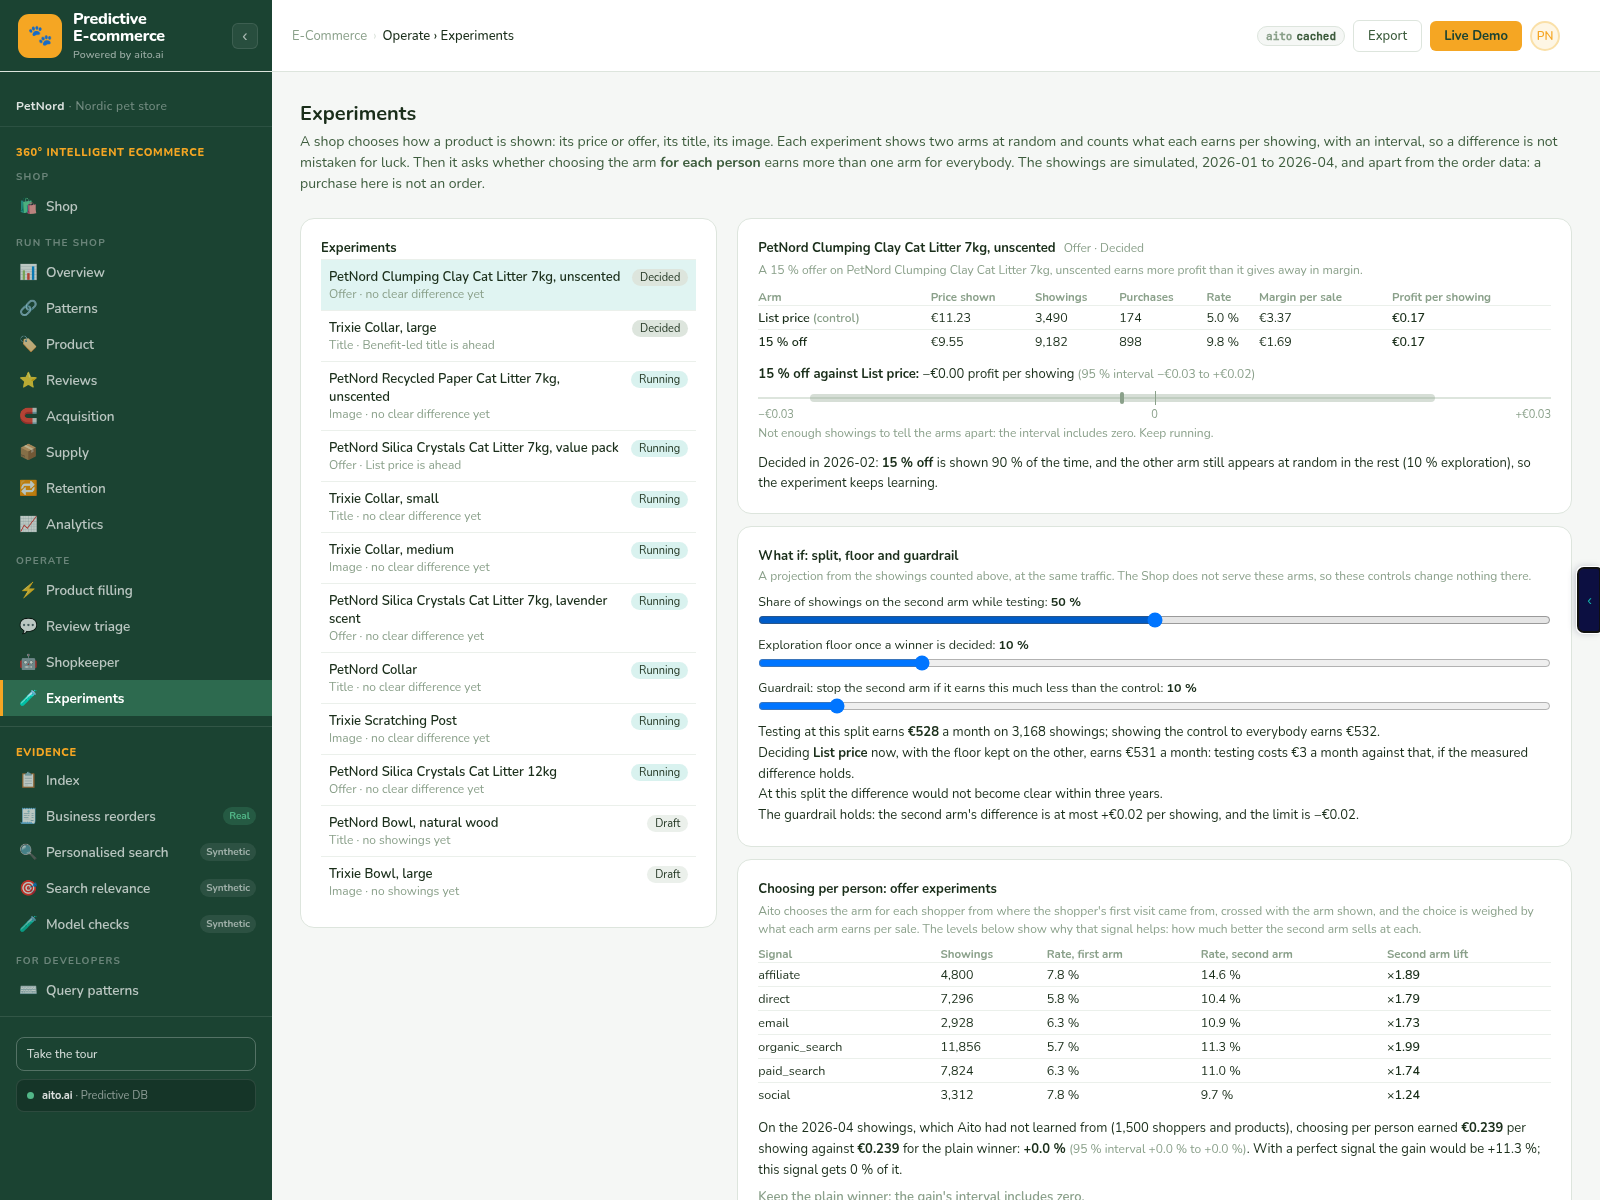
Each experiment stores its variants and every showing, with the shopper and whether they bought. The counts per arm come from Aito, and the difference of the second arm from the control is shown with a 95 % interval, so "no clear difference" is a reading, not a failure.
For choosing per person, _predict purchased given the shopper's signal and the arm shown is tested against the plain winner on a month it has not learned from. The page offers the per-person choice only where the interval is above zero and the gain is worth it, and says so where it is not. What-if controls project the split, the exploration floor and a guardrail from the counted arms.
For the full architecture, see the technology overview. For the broader narrative across multiple use cases, read The Predictive Application. For the whole picture, see predictive e-commerce.
See it live
This use case runs in the 🛒 E-commerce demo today. Click through to the live application and inspect the queries that produce the result.